Crawl4AI Cloud: the official hosted Crawl4AI API
Crawl4AI Cloud is the official hosted Crawl4AI API: a web scraping API for AI agents, by the team behind the open-source crawler. One key for pages and search.
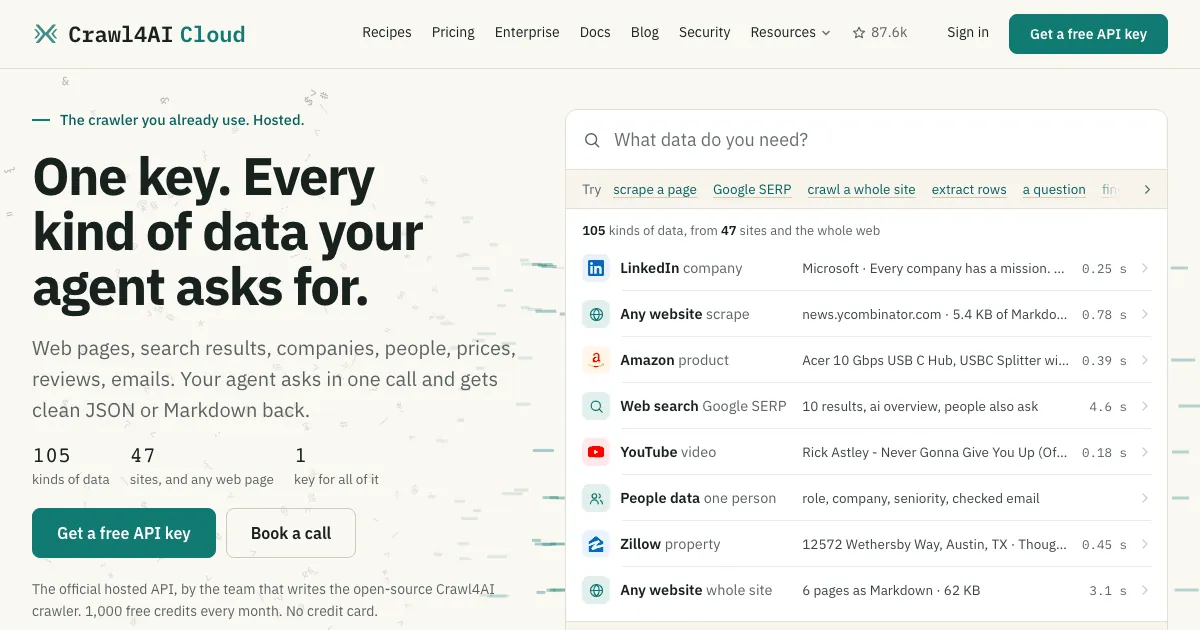
Crawl4AI started as a Python library: give it a URL, get back clean Markdown that a language model can read. It has more than 80,000 stars on GitHub. The library fetches pages well. The hard part starts when a crawler must run every day. So we built Crawl4AI Cloud. It is the same engine. We run the servers, the browsers and the proxies, and you send one HTTP call.
What a daily crawler needs
Pointing Crawl4AI at a URL on your laptop takes a minute. A crawler that runs every day, on many sites, needs more parts:
- a pool of real browsers, for pages that only show their text after JavaScript runs;
- proxies, for sites that block requests from data-center addresses;
- retries and fallbacks, for the request that fails at 3 a.m.;
- a queue and storage, once you go past a few hundred pages;
- and someone on the team who fixes it when a site changes its layout or starts blocking you.
None of it is the data you wanted.
If your job is small and stable (a few sites, plain HTML, nothing that blocks you), the free library on one small server is often the cheapest answer. Keep using it. Our build vs buy page does the math with public prices, and it has a calculator for your own numbers. To see how the API compares with Firecrawl and others, read our comparison.
What the Crawl4AI Cloud API does
One API key gives you every kind of data an agent usually asks for:
| Call | What you get back |
|---|---|
/scrape |
Any web page as clean Markdown or HTML |
/extract |
Structured JSON from a page, from a plain-English instruction or a schema |
/search |
Web search results, with the page text if you ask for it |
/serp (beta) |
Google's results page as data |
/answer (beta) |
A written answer to a question, with its sources |
/scan and /site |
A whole site: every URL it has, or every page as Markdown |
/monitors (Watch) |
A page checked on a schedule, with a message when it changes in the way you describe |
| Recipes | More than 90 ready-made scrapers that return rows from sites like Amazon, LinkedIn, Google Maps and YouTube |
Every call takes the same key and returns JSON. AI agents can also use all of it as tools through the hosted MCP server.
You do not choose how a page is fetched
For every site, the service tries the cheapest way that works:
- A recent copy that is already in our archive. It answers at once and costs half.
- A plain HTTP fetch. Most pages come back in 1 to 2 seconds.
- A real browser, only when the page needs one to show its text.
- For a site that fights back, our strongest method, priced higher.
You get the page and a note of how it was fetched, and you pay for the effort the page actually needed. A scrape that fails is not charged. If a site blocks every attempt, asks for a login, or times out, you get the reason and pay nothing.
Your first call
Get a free key on crawl4ai.com (no credit card), then:
export CRAWL4AI_KEY=sk_live_...
curl -s https://api.crawl4ai.com/scrape \
  -H "Authorization: Bearer $CRAWL4AI_KEY" -H "Content-Type: application/json" \
  -d '{"url":"https://example.com","format":"md"}'
The same call from Python:
import os
import requests

r = requests.post(
    "https://api.crawl4ai.com/scrape",
    headers={"Authorization": f"Bearer {os.environ['CRAWL4AI_KEY']}"},
    json={"url": "https://example.com", "format": "md"},
    timeout=120,
)
r.raise_for_status()
print(r.json()["markdown"])
Every option is in the scrape docs.
If you work in Claude Code, you can add the tools in one line, and your agent can call every endpoint as a tool:
claude mcp add --transport http --scope user crawl4ai \
  https://api.crawl4ai.com/mcp \
  --header "Authorization: Bearer $CRAWL4AI_KEY"
Cursor, Codex, Gemini CLI and other MCP clients work too. The setup for each one is in our llms.txt.
Keep the key in an environment variable, never in a file in your repository.
Crawl4AI Cloud pricing
- Free: 1,000 credits every month once you verify your email, at 10 requests a minute. No credit card.
- Starter: $10 a month for 10,000 credits and 120 requests a minute.
- Builder ($99 a month) and Scale ($499 a month) for bigger volumes, and custom plans above that.
One credit is $0.001. Extra credits you buy on a plan never expire, and a request that fails on our side is never charged. The live prices are always on the pricing page.
Is Crawl4AI still open source?
Yes. The library stays open source under the Apache-2.0 license, and it stays free. We still write and maintain it, and Crawl4AI Cloud runs the same engine. If you self-host today, your setup keeps working. You can use both: the library for simple jobs, the API for hard sites and high volume.
Your data
- Account, usage and billing records are kept in the EU. Our servers run in the US, the EU (Germany) and Singapore.
- We do not train models on your request content, and we do not sell customer data.
- GDPR and Singapore PDPA, with a data processing agreement on request. A SOC 2 Type I audit is in progress with an independent auditor, with a target of January 2027.
The details are on our security page.
Crawl4AI Cloud FAQ
Is Crawl4AI Cloud the official hosted service?
Yes. It is run by the team that writes the open-source Crawl4AI crawler. The site crawl4ai.org is not affiliated with Crawl4AI. The official addresses are crawl4ai.com, docs.crawl4ai.com and the GitHub repository.
Can I keep self-hosting?
Yes. When you self-host, you run the browsers, buy the proxies and keep up with sites that block you. Cloud does that work for you. To move a library setup to the API, see from the library to the cloud.
How much does the Crawl4AI API cost?
There is a free plan with 1,000 credits a month and no credit card. Paid plans start at $10 a month. One credit is $0.001.
How do agents connect?
Through the hosted MCP server or the REST API. Every endpoint is in the docs, and llms.txt holds the full API reference and the MCP setup in one file.
Try it
Get a free key, point it at the site that gives you the most trouble, and see what comes back. If something fails, is slow or is unclear, tell us at hello@crawl4ai.com.